Column Visibility Controls That Keep Non-Technical Teams Out of Sensitive Fields
Enforce column-level access controls to prevent non-technical teams from discovering sensitive data.
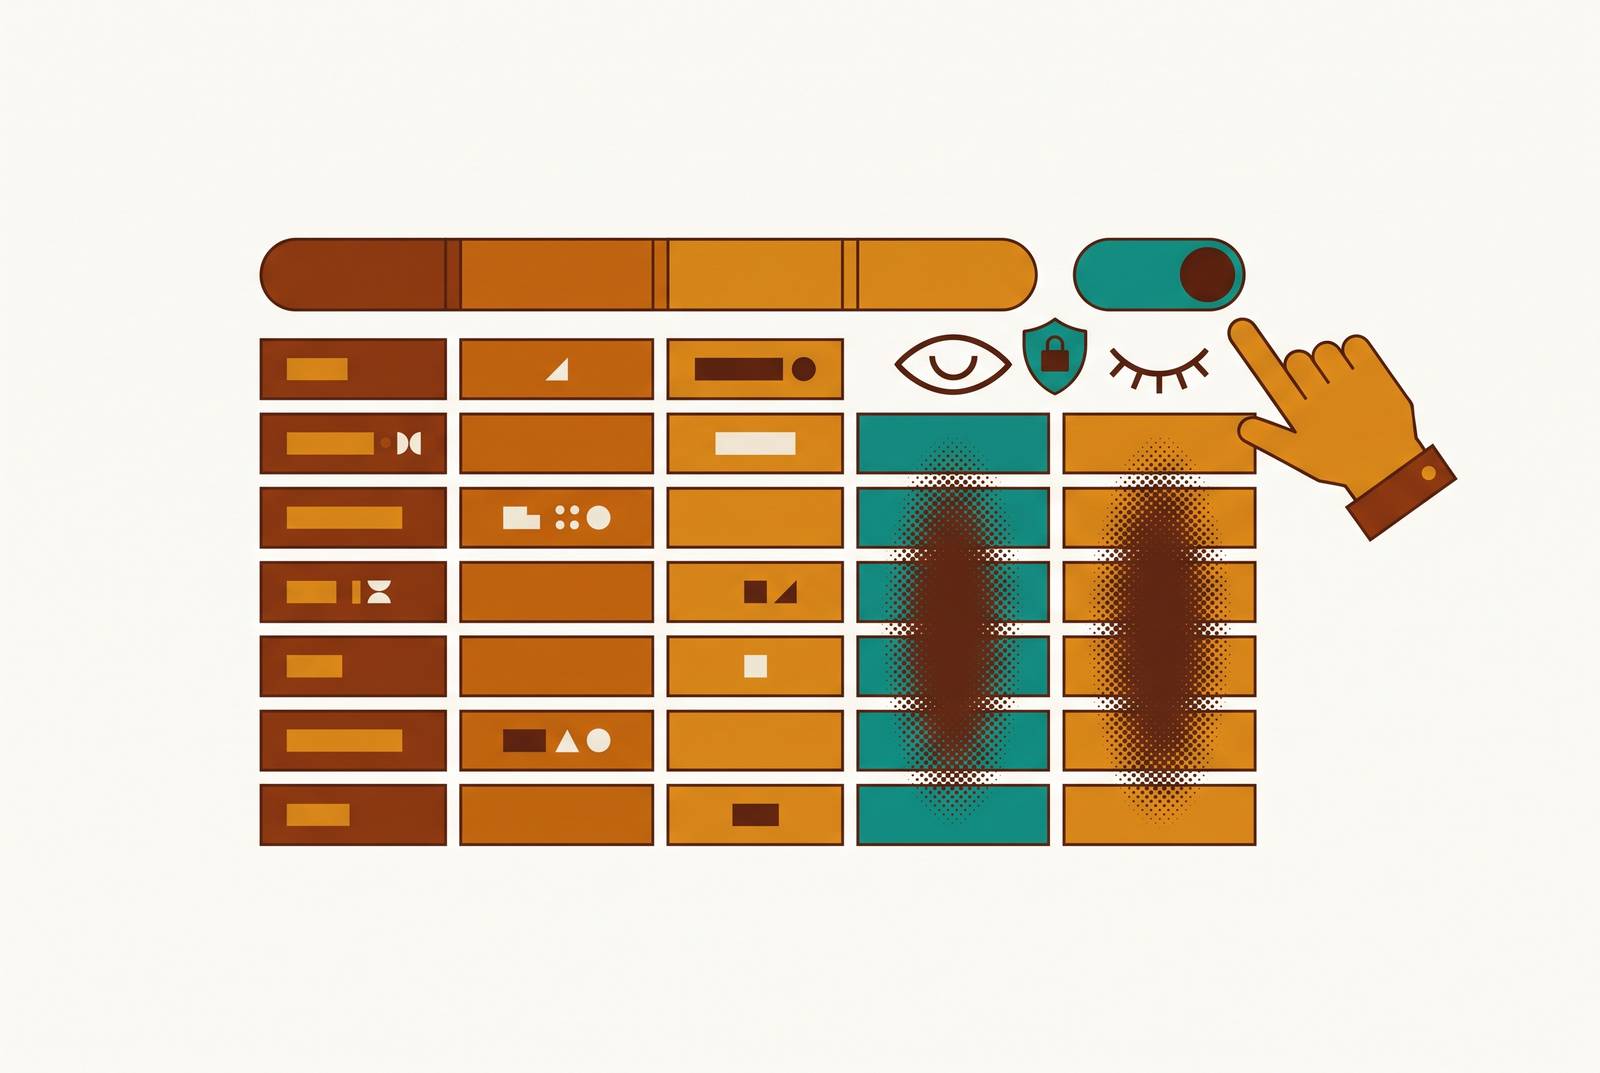
Column-level access control is the piece most self-serve BI rollouts skip. Teams grant read access to a table, then assume users will only look at the fields they need. That assumption collapses when someone opens a point-and-click interface and finds every column browsable. The fix is to define which fields each role can see at all, independent of the rows they can reach.
How to restrict which columns a non-technical team can see
The default database access model has a built-in mismatch. Granting a team access to a table grants them access to every column in it. That includes salaries, PII, and payment data those users have no legitimate reason to see.
Row-level security does not solve this. It filters which rows a user sees, not which columns. A support engineer allowed to see their region's orders can still read every customer's plaintext personal data in those records. Table-level grants are just as blunt. Read access to the orders table means read access to every field, including fields the granting engineer never thought about.
The gap is structural, not a configuration oversight. Most database access control was not designed to distinguish "this user needs order_status" from "this user can see every column in the row." And the exposure vector is not primarily malicious insiders. Log files, error messages, screenshots, and chat messages where team members paste data snippets for debugging all create real leakage from overly broad column access.
How self-serve analytics turns a latent gap into an active risk
Self-serve BI does not democratize data safely when column-level controls are missing. It democratizes exposure. Marketing, sales, HR, and support teams get direct query access to production tables. The assumption baked into most rollouts is that those users will only look at what they need. Nothing enforces that assumption.
Why does this matter in practice? When a non-SQL user connects to a table through a BI tool's point-and-click interface, every column in that table is browsable. The tool's friendly interface does not restrict what the underlying query can return. The user does not need to know SQL to see fields they should not.
AI natural-language query tools sharpen the problem further. An AI assistant that can construct and execute queries on behalf of a user can reach any column the user's session permits, at scale and without the human pausing to think about what they are asking for. Basedash's AI data privacy comparison documents whether each tool's AI assistant can only see the rows and columns the user can already see. The fact that this had to be researched at all shows how inconsistently it is implemented.
The governance failure runs in both directions. Too little control exposes sensitive fields. Too much restriction kills adoption and drives teams back to filing tickets or building spreadsheet workarounds. The question is not whether to restrict access, but where the restriction lives.
What column visibility controls actually do and where in the stack they can live
Column visibility controls are a distinct access-control primitive. They sit above row filtering and below table grants. They define which fields a given role can see at all, independent of which rows they can reach. Concretely, a support role might have row-level access to their region's customer records and column-level access to order_status, customer_id, and issue_description. But the columns holding payment card data, national IDs, or salary figures simply do not appear in their query surface.
Enforcement can happen at several layers, and where the control sits determines how strong it is. Database-native enforcement is the strongest. The restriction is applied by the query engine before any result is returned, regardless of which client, BI tool, notebook, or AI agent issued the query. A user with dataset access but without the required column permission gets an error, not a masked value.
Dynamic data masking is softer. Sensitive fields are returned but with values replaced by nulls, hashes, or tokens based on tagging rules. The column's existence is still visible, and the approach depends on consistent metadata tagging across datasets.
The BI application layer is weakest alone. Column restrictions configured inside the BI tool are real, but only for queries that flow through that tool. A user who connects to the underlying database through another client, a script, or an AI agent bypasses them entirely.
A consequential design choice sits inside this layer question. Column masking returns a null or hashed value. Column exclusion hides the column's existence from the schema entirely. Masking preserves schema visibility for debugging but leaves the field discoverable. Exclusion closes the surface completely but can break workflows that rely on wildcard selects or schema introspection.
The practical implication is straightforward. Application-layer controls alone are not sufficient for teams where users have, or could acquire, direct database connections. Database-native enforcement is the floor, not an optional enhancement. Row-level security filters which rows a user sees. It does nothing about which columns they see within those rows. That structural gap is what makes column-level controls a separate, necessary primitive alongside traditional database permissions.
Why AI query tools make column-level enforcement a hard requirement
AI query tools create a qualitatively new exposure surface. They can construct and execute queries that reach sensitive columns at machine speed, on behalf of users who never intended to request that data. When an AI assistant is given access to a schema it can query freely, it does not apply judgment about which columns are sensitive. It uses whatever columns help it answer the question, including ones the user should not see. Restricting the schema the model sees does not reliably fix this. Hiding unauthorized columns from the model's context can cause it to hallucinate those columns rather than refuse. That can actually increase the rate of unauthorized field access compared to leaving the schema visible. The correct answer is enforcement at or before the query compilation boundary, not prompt-level restriction.
This means the AI assistant must be subject to the same column-visibility policy as the human user. Ideally that enforcement happens at the database layer, so the policy applies regardless of whether a human, a BI dashboard, or an AI agent issues the query. Built for self-serve BI, Basedash makes column-level enforcement a foundation of query execution: which columns are reachable is decided before the query compiles, not after the tool returns results.
Shadow AI compounds the problem. Column visibility controls configured inside a sanctioned BI tool offer no protection if a team member pastes query results into a personal AI account. The control perimeter is the database session, not the application.
So what is the only answer that survives both direct connections and AI agents? Enforcement at the database layer. That is where the policy applies no matter which client issues the query. Anything less leaves a path around the control.
The compliance and governance obligations that column exposure creates
Copying or querying production data without restricting sensitive columns is a data processing activity. Major privacy regulations treat it as one, with specific obligations attached. GDPR Article 5's data minimization principle imposes obligations on who can access what data for what purpose. HIPAA's minimum necessary standard does the same. CCPA/CPRA's purpose-limitation and data minimization rules add a third requirement. A BI rollout that exposes salary or PII columns to anyone who can reach the table is structurally non-compliant with all three.
The compliance argument applies equally to analytics environments. Moving production data into a development, staging, or analytics copy without replacing sensitive fields does not remove the regulatory obligation. The data is still being processed.
Permission creep is the governance failure mode that audits catch most often. Access rights accumulate over time as team members change roles or take on temporary projects. Permissions set at rollout are rarely reviewed. Column-level controls are only as strong as the review cadence that keeps them current.
That raises an important question: how should temporary access work? Temporary access to sensitive columns should be request-based, with explicit approval and a defined expiration. Not an indefinite grant that outlasts the project that required it.
How to implement column visibility controls before a self-serve rollout
Column visibility controls work best when configured as a prerequisite to self-serve access, not retrofitted after a team has been browsing production data. Here is the sequence. Start with classification, not permissions. Run a sensitive-data discovery pass first to locate high-risk columns. PII, payment data, salaries, national IDs. You cannot restrict what you have not identified.
Attach policy controls to the classification tags directly. That way access control follows the data as columns are added, renamed, or moved. A permission tied to a column name breaks silently when the schema changes. A permission tied to a sensitivity tag propagates automatically.
Define role groups before rollout and map column visibility to those groups explicitly. Support sees these fields. Marketing sees these fields. HR sees these fields. Build the matrix in writing before touching any permissions configuration.
Enforce at the database layer where possible. Then validate that every access path is subject to the same policy. BI dashboards, direct database connections, AI assistants, scheduled exports, Slack integrations. Application-layer controls that can be bypassed by a different client are not controls.
Verify AI query coverage specifically. Confirm in the BI tool's documentation or security review that AI-generated queries are limited to the columns the user's role is permitted to see. Not the full schema the model was trained or prompted with.
Build a review schedule into the rollout plan. Permissions set once and never revisited accumulate into a compliance liability. Quarterly access reviews with a defined owner are the minimum.
What to look for when a BI tool claims column-level controls
The right question when evaluating a BI tool for self-serve rollout is not whether it has column-level controls. It is where those controls are enforced and whether AI-generated queries are subject to the same policy as human-issued ones. Start with the enforcement-layer test. Does the tool enforce column restrictions at the database query level, or only inside its own interface? A tool that controls columns only within its UI leaves every other access path unrestricted. Direct connections, scripts, AI agents. All open.
Then apply the AI coverage test. Does the tool document explicitly that its AI assistant is limited to the columns the user is permitted to see? Tools that are silent on this should be treated as unconfirmed until the vendor answers in writing. Basedash's 2026 AI data privacy comparison records, for each of 12 BI tools, whether the AI assistant is limited to the user's permitted rows and columns, and whether AI is on by default and can be toggled by admins. It is a useful starting point for the security review because it turns a vendor's silence into a question you can ask.
Plan gating matters too. Basedash's BI security-by-plan comparison, verified September 23, 2026, documents which plan tier unlocks row-level security, SSO, SCIM, and audit logs across a range of tools. Column and row controls are often gated on the same plan tier. The cheapest tier rarely includes the governance features that a secure rollout requires. Basedash's RLS comparison covers enforcement layer, identity integration, embedded support, AI query coverage, and plan gating for tools with strong row-level security 23. The same criteria apply directly to evaluating column-level controls.
Minimum data access for a non-technical team before go-live
A self-serve rollout is safe to proceed when every access path is governed by the same column-visibility policy, reviewed by a named owner, and documented well enough to show an auditor. Here is the minimum checklist. Every sensitive column is classified and tagged before any non-technical user connects. Role-to-column access is defined in writing and mapped to identity provider groups, not to individual user accounts that change when someone leaves or changes roles.
The enforcement layer is confirmed at the database, not assumed from the BI tool's interface. Every access path has been tested against the policy. Dashboard, export, AI assistant, Slack integration, direct connection. AI query coverage is confirmed in writing from the vendor. The AI assistant cannot return columns the user's role cannot see. A review schedule exists with a named owner. Access granted today without a review date becomes a compliance liability within one employee turnover cycle. Audit logging is on and being reviewed, not just enabled. An audit log that no one reads does not catch permission creep.
None of this restricts self-serve access. It makes broad access safe enough to extend to the whole company. Column visibility controls are the layer that lets you say yes to more people, more confidently.